Today's highlights
- Subscriptions and APIs both loosen: Codex delivers yesterday's teaser — every Pro tier plus Business Premium doubles, and the Pro 200 cut is walked back; Anthropic raises Claude API per-request size to 128 MB for long computer-use traces and big PDFs.
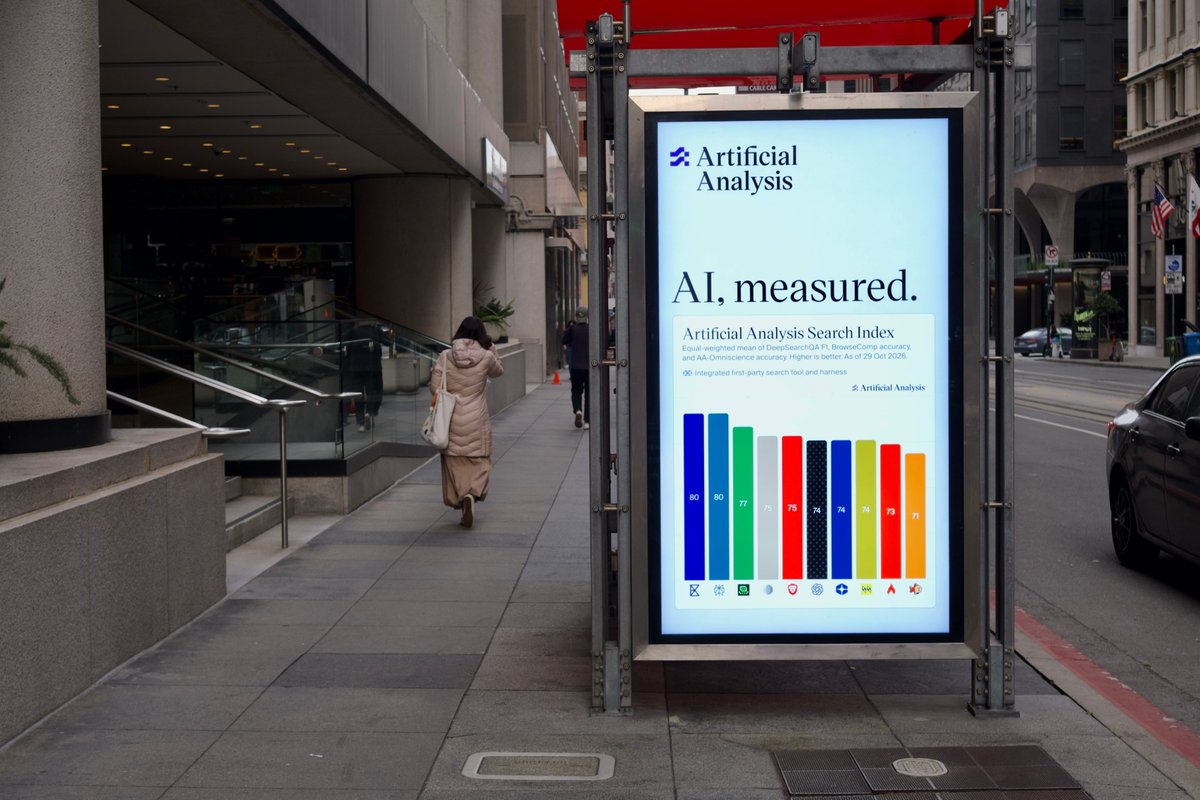
- Open weights meet fresh boards: Mistral Large 4 (Le Chonk) ships weights; Artificial Analysis adds an HLE-Diamond board and a Search Index so hard exams and "which search API for agents" become comparable products.
- How people drive agents is the methodology story: Thariq on coding-agent mania as avoidance; Mainplane's measured case against Compaction; Jules winding down into Antigravity — the tools change, and so do the habits.
1. Codex Day 25: all Pro tiers double; Pro 200 cut cancelled
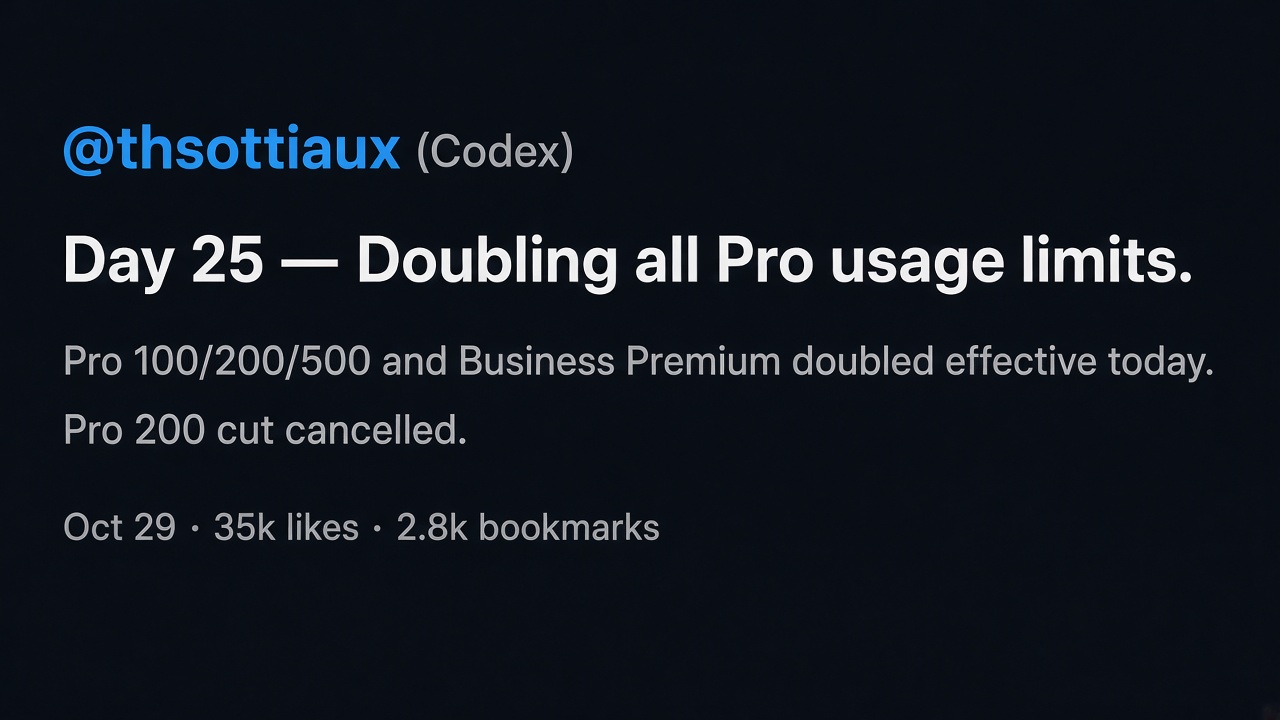
Takeaways: @thsottiaux (Codex) posts Day 25: effective today, Pro 100 / 200 / 500 and Business Premium usage caps all double; the planned Pro 200 reduction is cancelled, so Work and Codex quotas stay the same; extended limits for dots continue for now and remain separate from default usage. @dotey mirrors the Chinese read: Plus is not on the list, and prices are unchanged.
Why it matters: This closes the 10-29 "good news tomorrow" loop and answers anxiety about tighter legacy Pro 200 — the narrative flips from "cut" to "double + no cut," cooling short-term compute panic.
- thsottiaux: Day 25 launch: https://x.com/thsottiaux/status/2115850175868727621
- dotey: CN summary (tier math): https://x.com/dotey/status/2115856411439575386
2. Claude API: per-request size 32 MB → 128 MB
Takeaways: @ClaudeDevs raises the max request size for Messages and Token Counting on the Claude API from 32 MB to 128 MB (~4×). The stated reason is concrete: image-heavy computer-use sessions and large PDFs were hitting 32 MB with context window still left. @dotey notes this applies to the official Anthropic API.
Why it matters: This is not another "longer context" claim — it treats multimodal / tool-trace payload size as the real bottleneck. Anyone running long screenshot agents feels it first.
- ClaudeDevs: announcement: https://x.com/ClaudeDevs/status/2115923971279614171
- dotey: CN note: https://x.com/dotey/status/2115968852349567254
3. Thariq: coding-agent mania is often avoidance
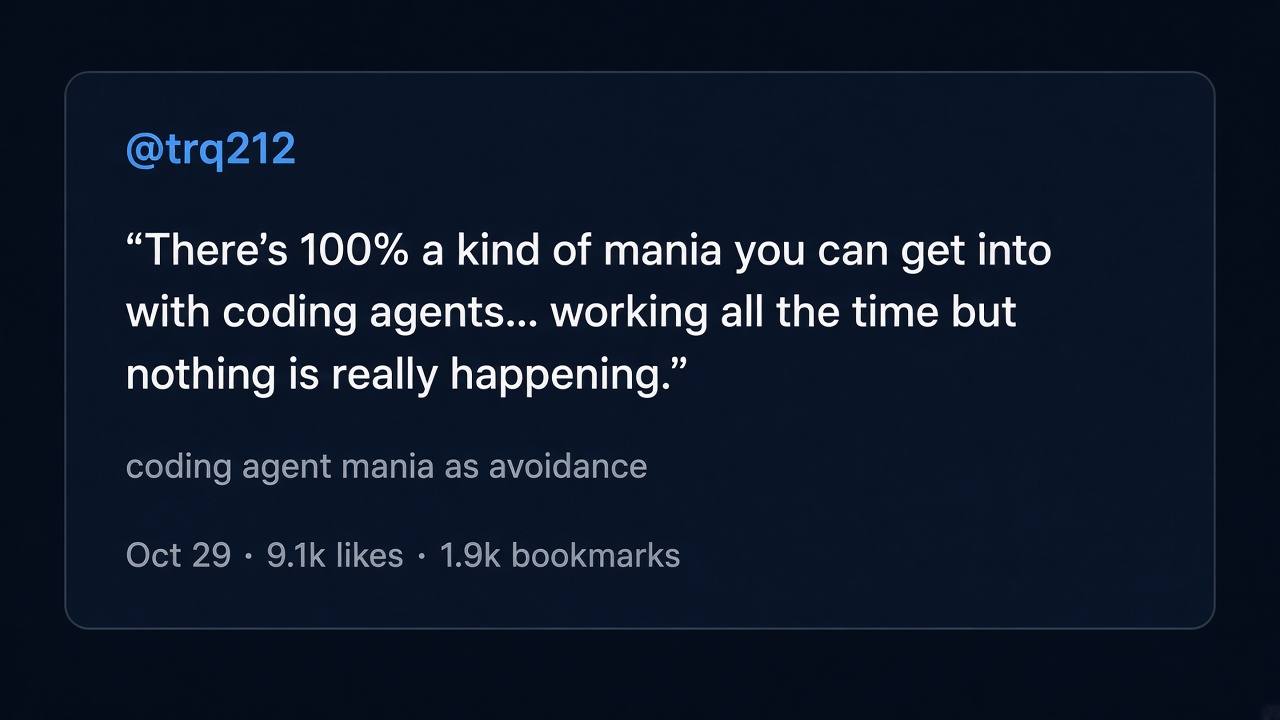
Takeaways: Anthropic's @trq212 (Thariq) writes that there is "100% a kind of mania" you can fall into with coding agents — it feels like you are getting a lot done and working all the time, yet nothing is really happening. He frames it as often a form of avoidance of something else in life. The post clears 9k likes and ~1.9k bookmarks; replies split between "called out" and "this is normal exploration."
Why it matters: On a day of rising models and quotas, a product insider aims the camera at user psychology — throughput theater is not delivery, and that correction is more useful than another leaderboard screenshot.
- trq212: original: https://x.com/trq212/status/2115937378674372783
4. Mistral Large 4 (Le Chonk): open weights ship
Takeaways: @MistralAI releases weights for an improved Le Chonk, pitched for agentic coding and cybersecurity; it claims #1 among open models on @cognition's FrontierCode and cites defensive evals with vendors including CrowdStrike and Cloudflare. @ArtificialAnlys corroborates: Large 4 is now the #1 open-weights model developed outside China (~1.05T total / 52B active); on the Coding Agent Index in Mistral Vibe it scores ~48 among current open weights while using fewer tokens. Weights are on Hugging Face under a modified MIT license (MaaS needs a separate commercial license) — the "just open-sourced" claim checks out against the official post, not rumor.
Why it matters: A day after closed models dominated Carbon / Fusion chatter, Europe's flagship open release competes on self-host + token efficiency, with a third-party board on the same screen.
- MistralAI: weights launch: https://x.com/MistralAI/status/2115811242556137820
- ArtificialAnlys: open-weights read: https://x.com/ArtificialAnlys/status/2115820547103952925
- ArtificialAnlys: Coding Agent Index: https://x.com/ArtificialAnlys/status/2115820551675789731
5. OpenCode Go Teams: whole-team access at about USD 20 / member / month
Takeaways: @opencode announces OpenCode Go is now available to entire teams. The product page lists Go at USD 10/mo, Go Plus at USD 40/mo, and Go Teams at USD 20 / member / month, with a demo video. The pitch is a low-cost team door to leading coding models — not another solo CLI.
Why it matters: After individual price wars, the next battlefield is seat-based packaging — whoever makes "one quota per member" the default purchase unit wins the trial shortlist.
- opencode: Go Teams launch: https://x.com/opencode/status/2115898662622462126
6. Anthropic: Claude "self-assessment" against misuse
Takeaways: @AnthropicAI describes self-assessment: right after each reply, Claude gives a preliminary safety read of the conversation. In use since June, it has surfaced misuse other safeguards were not designed to catch. Because Claude already read the thread, the extra compute is efficient; unlike discrete classifiers, accuracy rides the base model upward. @dotey's CN notes: Anthropic pays the compute (not billed to users), no extra data collection, and a single flag is said not to auto-ban.
Why it matters: Safety moves from bolt-on classifiers toward model self-review — heavy coding / agent users should expect more silent checks between turns, which is also why official posts stress "we pay for it."
- AnthropicAI: announcement: https://x.com/AnthropicAI/status/2115871889549865429
- dotey: CN summary: https://x.com/dotey/status/2115923359149998490
7. Jules winds down; learnings move into Antigravity
Takeaways: @julesagent recaps Jules as an experiment in asynchronous coding agents whose learnings shaped several products across Google. Next, those learnings move into @antigravity so users get both autonomous remote background tasks and an agent-first development environment. As focus shifts to that unified experience, Jules will be winding down. No hard shutdown date is stated in the post; reactions split between missing async bug-crushing and looking ahead to Antigravity.
Why it matters: Classic platform consolidation — async agents stop living as a standalone app and become capabilities inside an IDE / remote-task stack. Do not treat Jules as a long-term independent line.
- julesagent: wind-down note: https://x.com/julesagent/status/2115883717705261283
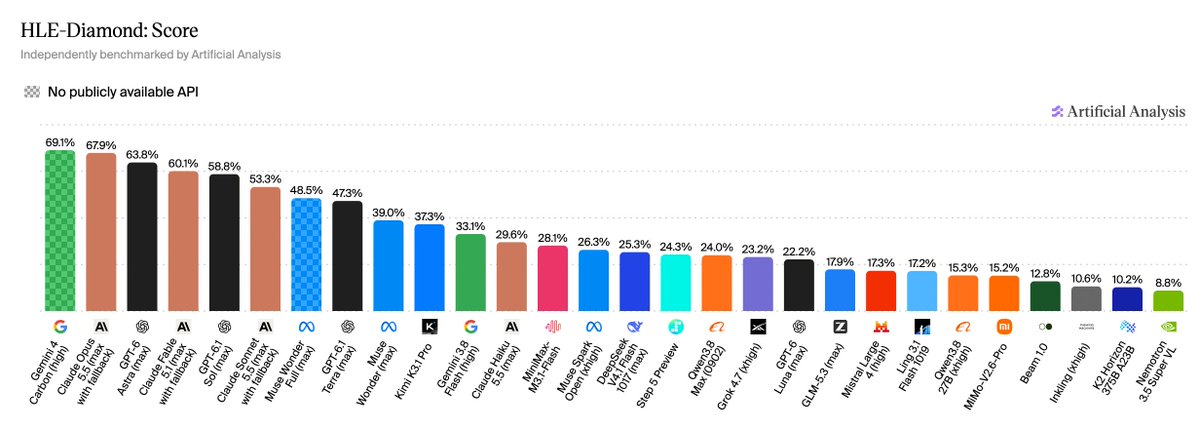
8. Artificial Analysis: HLE-Diamond leaderboard
Takeaways: @ArtificialAnlys launches an independent HLE-Diamond board (part of Intelligence Index v5) on CAIS / Scale AI's refined 1,000-question Humanity's Last Exam (reasoning / knowledge split; 272 with images). Protocol: no tools, official system prompt, GPT-5.6 Luna (medium) grading with the official HLE judge prompt (pass@1). Takeaways: only ~13% of variants clear 50%; Gemini 4 Carbon (high) leads at 69%, Claude Opus 5.5 (max) at 68%; models are stronger on reasoning than knowledge; open weights trail closed by 30+ points. A follow-up shows effort knobs: Opus 5.5 low→max gains ~26 points at ~35× cost.
Why it matters: After Index v5 made private datasets the majority, HLE-Diamond turns "humanity's last exam" into a reproducible board — Carbon and Opus stay neck-and-neck, while the open-weights gap is hard to spin away.
- ArtificialAnlys: HLE-Diamond launch: https://x.com/ArtificialAnlys/status/2115989388689813945
- ArtificialAnlys: effort / cost follow-up: https://x.com/ArtificialAnlys/status/2115989392695374188
9. The Compaction debate: lossy summary vs on-demand retrieval
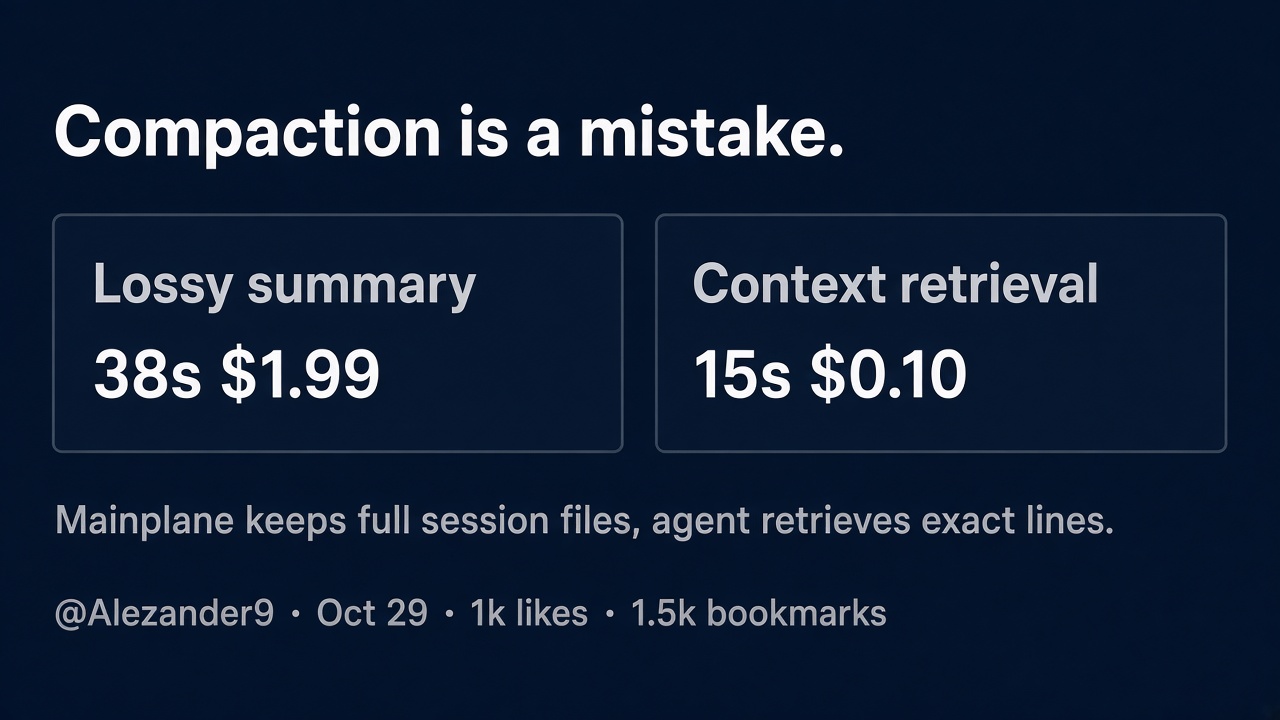
Takeaways: @Alezander9 argues 「Compaction is a mistake」: when context fills, tools like Codex and Claude Code prefill the session, write a summary, and start a new session from it. On a real ~400k-token Opus 5.5 session he measures ~38 s / USD 1.99 with a cold prompt cache and ~29 s / USD 0.17 with a hit — and the summary is lossy. Mainplane inverts the pattern: keep the full session as a file; start a new session immediately with "retrieve key context as you go." Same session, same model: ~15 s / USD 0.10, cache-independent, no paraphrase. Mainplane claims MIT open source. Bookmarks (~1564) beat likes — classic methodology-archive spread. @dotey later compares Claude Code's post-compact on-demand reload with Mainplane's approach.
Why it matters: Long-session cost is not just the token sticker — it is "which exact error line the summary erased." Moving memory from "model summary" to "tool retrieval" is the bitter lesson applied at the harness layer.
- Alezander9: long post: https://x.com/Alezander9/status/2115842962521509968
- dotey: Claude Code compact comparison: https://x.com/dotey/status/2116026448234332315
10. Artificial Analysis Search Index: pick a search API for agents
Takeaways: @ArtificialAnlys launches the Search Index: same base model and harness across ~1700 tasks plus BrowseComp, DeepSearchQA, and AA-Omniscience, measuring Search API quality, cost, and latency. Thesis: by year-end agents may search the web more than humans. Today Exa (auto) and Perplexity (medium) lead with their best configs (~80).
Why it matters: Beyond coding agents, "which search API" is becoming a comparable infrastructure choice — the Search Index pulls marketing "better search" claims onto one board.
- ArtificialAnlys: Search Index launch: https://x.com/ArtificialAnlys/status/2115970517778002283